
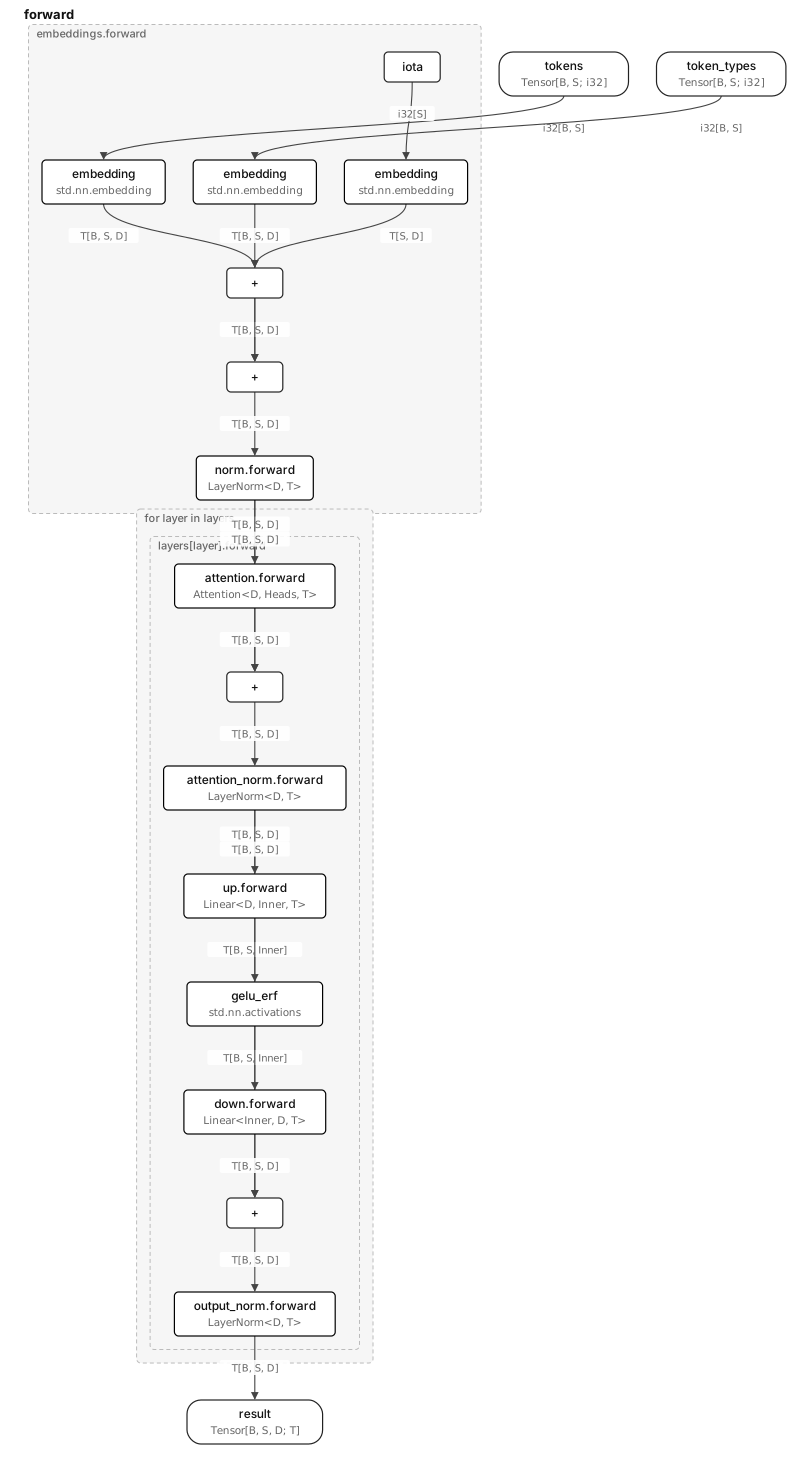
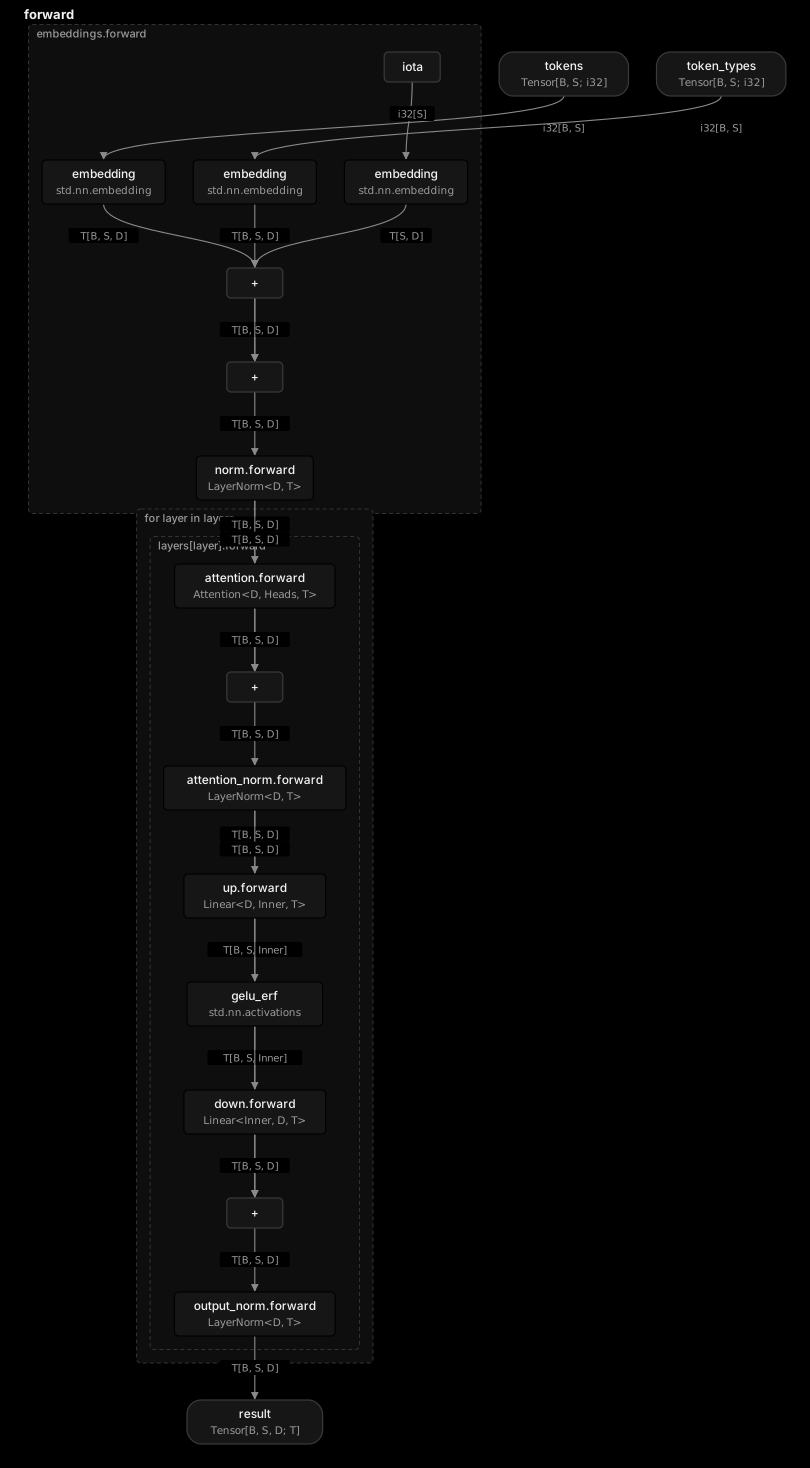
The forward entry with one level of blocks expanded. Every edge carries the tensor type the compiler inferred at that point, in the model's own generics.
Entries
| Entry | Signature |
|---|---|
forward | forward<B: Dim, S: Dim>(tokens: Tensor[B, S; i32], token_types: Tensor[B, S; i32]) -> Tensor[B, S, D; T] |
embed | embed<B: Dim, S: Dim>(tokens: Tensor[B, S; i32], token_types: Tensor[B, S; i32]) -> Tensor[B, D; f32] |
Generics
The root block's generics as this checkpoint binds them.
Vocab | 30522 |
MaxPositions | 512 |
TypeVocab | 2 |
D | 384 |
Heads | 12 |
Inner | 1536 |
Layers | 6 |
T | f32 |
Blocks
Every block of the program with its members and functions, as linnet inspect prints them.
Attention
text
minilm::Attention<D: Dim, Heads: Dim, T: Float>
  sub query: Linear<D, D, T>
  sub key: Linear<D, D, T>
  sub value: Linear<D, D, T>
  sub out: Linear<D, D, T>
  pub fn forward<B: Dim, S: Dim>(x: Tensor[B, S, D; T]) -> Tensor[B, S, D; T]
Embedding
text
std.nn.embedding::Embedding<Vocab: Dim, H: Dim, T: Float = bf16>
  param weight: Tensor[Vocab, H; T]
  pub fn forward<*S: Shape>(ids: Tensor[*S; i32]) -> Tensor[*S, H; T]
Embeddings
text
minilm::Embeddings<Vocab: Dim, MaxPositions: Dim, TypeVocab: Dim, D: Dim, T: Float>
  param word_embeddings: Tensor[Vocab, D; T]
  param position_embeddings: Tensor[MaxPositions, D; T]
  param token_type_embeddings: Tensor[TypeVocab, D; T]
  sub norm: LayerNorm<D, T>
  pub fn forward<B: Dim, S: Dim>(tokens: Tensor[B, S; i32], token_types: Tensor[B, S; i32]) -> Tensor[B, S, D; T]
EncoderLayer
text
minilm::EncoderLayer<D: Dim, Heads: Dim, Inner: Dim, T: Float>
  sub attention: Attention<D, Heads, T>
  sub attention_norm: LayerNorm<D, T>
  sub up: Linear<D, Inner, T>
  sub down: Linear<Inner, D, T>
  sub output_norm: LayerNorm<D, T>
  pub fn forward<B: Dim, S: Dim>(x: Tensor[B, S, D; T]) -> Tensor[B, S, D; T]
LayerNorm
text
minilm::LayerNorm<D: Dim, T: Float>
  param weight: Tensor[D; T]
  param bias: Tensor[D; T]
  pub fn forward<*S: Shape>(x: Tensor[*S, D; T]) -> Tensor[*S, D; T]
Linear
text
std.nn.linear::Linear<In: Dim, Out: Dim, T: Float = bf16>
  param weight: Tensor[Out, In; T]
  param bias: Tensor[Out; T]?
  pub fn forward<*S: Shape>(x: Tensor[*S, In; T]) -> Tensor[*S, Out; T]
Model
text
minilm::Model<Vocab: Dim, MaxPositions: Dim, TypeVocab: Dim, D: Dim, Heads: Dim, Inner: Dim, Layers: Dim, T: Float = f32>
  sub embeddings: Embeddings<Vocab, MaxPositions, TypeVocab, D, T>
  sub layers: [EncoderLayer<D, Heads, Inner, T>; Layers]
  pub entry forward<B: Dim, S: Dim>(tokens: Tensor[B, S; i32], token_types: Tensor[B, S; i32]) -> Tensor[B, S, D; T]
  pub entry embed<B: Dim, S: Dim>(tokens: Tensor[B, S; i32], token_types: Tensor[B, S; i32]) -> Tensor[B, D; f32]
RmsNorm
text
std.nn.norm::RmsNorm<H: Dim, T: Float = bf16>
  param weight: Tensor[H; T]
  pub fn forward<*S: Shape>(x: Tensor[*S, H; T]) -> Tensor[*S, H; T]