
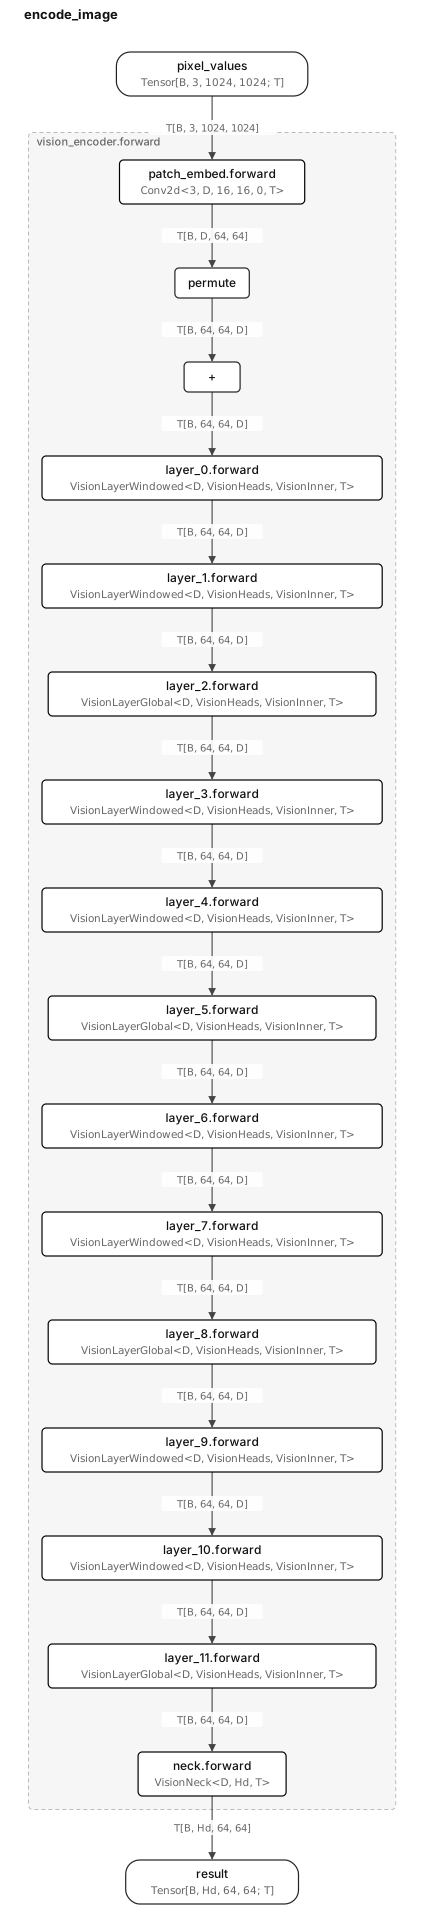
The encode_image entry with one level of blocks expanded. Every edge carries the tensor type the compiler inferred at that point, in the model's own generics.
Entries
| Entry | Signature |
|---|---|
encode_image | encode_image<B: Dim>(pixel_values: Tensor[B, 3, 1024, 1024; T]) -> Tensor[B, Hd, 64, 64; T] |
decode_points | decode_points<B: Dim, Pts: Dim, N: Dim>(image_embeddings: Tensor[B, Hd, 64, 64; T], input_points: Tensor[B, Pts, N, 2; T], input_labels: Tensor[B, Pts, N; i32]) -> (Tensor[B, Pts, 4, 256, 256; T], Tensor[B, Pts, 4; T]) |
decode_boxes | decode_boxes<B: Dim, Nb: Dim>(image_embeddings: Tensor[B, Hd, 64, 64; T], input_boxes: Tensor[B, Nb, 4; T]) -> (Tensor[B, Nb, 4, 256, 256; T], Tensor[B, Nb, 4; T]) |
Generics
The root block's generics as this checkpoint binds them.
D | 768 |
VisionHeads | 12 |
VisionInner | 3072 |
Hd | 256 |
MaskHeads | 8 |
MaskInner | 2048 |
T | f32 |
Blocks
Every block of the program with its members and functions, as linnet inspect prints them.
Conv1d
text
std.nn.conv::Conv1d<Cin: Dim, Cout: Dim, K: Dim, Stride: Dim, Pad: Dim, T: Float = f32>
  param weight: Tensor[Cout, Cin, K; T]
  param bias: Tensor[Cout; T]?
  pub fn forward<B: Dim, L: Dim>(x: Tensor[B, Cin, L; T]) -> Tensor[B, Cout, 1 + (-1 * K + L + 2 * Pad) / Stride; T]
Conv2d
text
std.nn.conv::Conv2d<Cin: Dim, Cout: Dim, K: Dim, Stride: Dim, Pad: Dim, T: Float = f32>
  param weight: Tensor[Cout, Cin, K, K; T]
  param bias: Tensor[Cout; T]?
  pub fn forward<B: Dim, H: Dim, W: Dim>(x: Tensor[B, Cin, H, W; T]) -> Tensor[B, Cout, 1 + (-1 * K + H + 2 * Pad) / Stride, 1 + (-1 * K + W + 2 * Pad) / Stride; T]
Conv2dRect
text
std.nn.conv::Conv2dRect<Cin: Dim, Cout: Dim, KH: Dim, KW: Dim, StrideH: Dim, StrideW: Dim, PadH: Dim, PadW: Dim, T: Float = f32>
  param weight: Tensor[Cout, Cin, KH, KW; T]
  param bias: Tensor[Cout; T]?
  pub fn forward<B: Dim, H: Dim, W: Dim>(x: Tensor[B, Cin, H, W; T]) -> Tensor[B, Cout, 1 + (-1 * KH + H + 2 * PadH) / StrideH, 1 + (-1 * KW + W + 2 * PadW) / StrideW; T]
Deconv2x2
text
sam::Deconv2x2<Cin: Dim, Cout: Dim, T: Float>
  param weight: Tensor[Cin, Cout, 2, 2; T]
  param bias: Tensor[Cout; T]
  pub fn forward<B: Dim, H: Dim, W: Dim>(x: Tensor[B, Cin, H, W; T]) -> Tensor[B, Cout, 2 * H, 2 * W; T]
FeedForward3
text
sam::FeedForward3<In: Dim, Hidden: Dim, Out: Dim, T: Float>
  sub proj_in: Linear<In, Hidden, T>
  sub hidden: Linear<Hidden, Hidden, T>
  sub proj_out: Linear<Hidden, Out, T>
  pub fn forward<*S: Shape>(x: Tensor[*S, In; T]) -> Tensor[*S, Out; T]
GeluMlp
text
sam::GeluMlp<D: Dim, Inner: Dim, T: Float>
  sub lin1: Linear<D, Inner, T>
  sub lin2: Linear<Inner, D, T>
  pub fn forward<*S: Shape>(x: Tensor[*S, D; T]) -> Tensor[*S, D; T]
LayerNorm
text
sam::LayerNorm<D: Dim, T: Float>
  param weight: Tensor[D; T]
  param bias: Tensor[D; T]
  pub fn forward<*S: Shape>(x: Tensor[*S, D; T]) -> Tensor[*S, D; T]
LayerNormCHW
text
sam::LayerNormCHW<C: Dim, T: Float>
  param weight: Tensor[C; T]
  param bias: Tensor[C; T]
  pub fn forward<B: Dim, H: Dim, W: Dim>(x: Tensor[B, C, H, W; T]) -> Tensor[B, C, H, W; T]
Linear
text
std.nn.linear::Linear<In: Dim, Out: Dim, T: Float = bf16>
  param weight: Tensor[Out, In; T]
  param bias: Tensor[Out; T]?
  pub fn forward<*S: Shape>(x: Tensor[*S, In; T]) -> Tensor[*S, Out; T]
MaskAttention
text
sam::MaskAttention<Hd: Dim, Internal: Dim, Heads: Dim, T: Float>
  sub q_proj: Linear<Hd, Internal, T>
  sub k_proj: Linear<Hd, Internal, T>
  sub v_proj: Linear<Hd, Internal, T>
  sub out_proj: Linear<Internal, Hd, T>
  pub fn forward<B: Dim, Pts: Dim, Q: Dim, K: Dim>(query: Tensor[B, Pts, Q, Hd; T], key: Tensor[B, Pts, K, Hd; T], value: Tensor[B, Pts, K, Hd; T]) -> Tensor[B, Pts, Q, Hd; T]
MaskDecoder
text
sam::MaskDecoder<Hd: Dim, Heads: Dim, Inner: Dim, T: Float>
  param iou_token: Tensor[1, Hd; T]
  param mask_tokens: Tensor[4, Hd; T]
  sub transformer: TwoWayTransformer<Hd, Heads, Inner, T>
  sub upscale_conv1: Deconv2x2<Hd, Hd / 4, T>
  sub upscale_layer_norm: LayerNormCHW<Hd / 4, T>
  sub upscale_conv2: Deconv2x2<Hd / 4, Hd / 8, T>
  sub hyper_mlp_0: FeedForward3<Hd, Hd, Hd / 8, T>
  sub hyper_mlp_1: FeedForward3<Hd, Hd, Hd / 8, T>
  sub hyper_mlp_2: FeedForward3<Hd, Hd, Hd / 8, T>
  sub hyper_mlp_3: FeedForward3<Hd, Hd, Hd / 8, T>
  sub iou_prediction_head: FeedForward3<Hd, Hd, 4, T>
  pub fn forward<B: Dim, Pts: Dim, Ns: Dim>(image_embeddings: Tensor[B, Hd, 64, 64; T], image_pe: Tensor[B, Hd, 64, 64; T], sparse_prompt_embeddings: Tensor[B, Pts, Ns, Hd; T], dense_prompt_embeddings: Tensor[B, Hd, 64, 64; T]) -> (Tensor[B, Pts, 4, 256, 256; T], Tensor[B, Pts, 4; T])
Model
text
sam::Model<D: Dim, VisionHeads: Dim, VisionInner: Dim, Hd: Dim, MaskHeads: Dim, MaskInner: Dim, T: Float = f32>
  sub vision_encoder: VisionEncoder<D, VisionHeads, VisionInner, Hd, T>
  param positional_embedding: Tensor[2, Hd / 2; T]
  param not_a_point_embed: Tensor[1, Hd; T]
  param point_embed_0: Tensor[1, Hd; T]
  param point_embed_1: Tensor[1, Hd; T]
  param point_embed_2: Tensor[1, Hd; T]
  param point_embed_3: Tensor[1, Hd; T]
  param no_mask_embed: Tensor[1, Hd; T]
  sub mask_decoder: MaskDecoder<Hd, MaskHeads, MaskInner, T>
  pub entry encode_image<B: Dim>(pixel_values: Tensor[B, 3, 1024, 1024; T]) -> Tensor[B, Hd, 64, 64; T]
  pub entry decode_points<B: Dim, Pts: Dim, N: Dim>(image_embeddings: Tensor[B, Hd, 64, 64; T], input_points: Tensor[B, Pts, N, 2; T], input_labels: Tensor[B, Pts, N; i32]) -> (Tensor[B, Pts, 4, 256, 256; T], Tensor[B, Pts, 4; T])
  pub entry decode_boxes<B: Dim, Nb: Dim>(image_embeddings: Tensor[B, Hd, 64, 64; T], input_boxes: Tensor[B, Nb, 4; T]) -> (Tensor[B, Nb, 4, 256, 256; T], Tensor[B, Nb, 4; T])
ReluMlp
text
sam::ReluMlp<D: Dim, Inner: Dim, T: Float>
  sub lin1: Linear<D, Inner, T>
  sub lin2: Linear<Inner, D, T>
  pub fn forward<*S: Shape>(x: Tensor[*S, D; T]) -> Tensor[*S, D; T]
RmsNorm
text
std.nn.norm::RmsNorm<H: Dim, T: Float = bf16>
  param weight: Tensor[H; T]
  pub fn forward<*S: Shape>(x: Tensor[*S, H; T]) -> Tensor[*S, H; T]
TwoWayAttentionBlock
text
sam::TwoWayAttentionBlock<Hd: Dim, Heads: Dim, Inner: Dim, T: Float>
  sub self_attn: MaskAttention<Hd, Hd, Heads, T>
  sub layer_norm1: LayerNorm<Hd, T>
  sub cross_attn_token_to_image: MaskAttention<Hd, Hd / 2, Heads, T>
  sub layer_norm2: LayerNorm<Hd, T>
  sub mlp: ReluMlp<Hd, Inner, T>
  sub layer_norm3: LayerNorm<Hd, T>
  sub cross_attn_image_to_token: MaskAttention<Hd, Hd / 2, Heads, T>
  sub layer_norm4: LayerNorm<Hd, T>
  pub fn forward_first<B: Dim, Pts: Dim, Nq: Dim, Nk: Dim>(queries: Tensor[B, Pts, Nq, Hd; T], keys: Tensor[B, Pts, Nk, Hd; T], qpe: Tensor[B, Pts, Nq, Hd; T], kpe: Tensor[B, Pts, Nk, Hd; T]) -> (Tensor[B, Pts, Nq, Hd; T], Tensor[B, Pts, Nk, Hd; T])
  pub fn forward_rest<B: Dim, Pts: Dim, Nq: Dim, Nk: Dim>(queries: Tensor[B, Pts, Nq, Hd; T], keys: Tensor[B, Pts, Nk, Hd; T], qpe: Tensor[B, Pts, Nq, Hd; T], kpe: Tensor[B, Pts, Nk, Hd; T]) -> (Tensor[B, Pts, Nq, Hd; T], Tensor[B, Pts, Nk, Hd; T])
  fn tail<B: Dim, Pts: Dim, Nq: Dim, Nk: Dim>(queries: Tensor[B, Pts, Nq, Hd; T], keys: Tensor[B, Pts, Nk, Hd; T], qpe: Tensor[B, Pts, Nq, Hd; T], kpe: Tensor[B, Pts, Nk, Hd; T]) -> (Tensor[B, Pts, Nq, Hd; T], Tensor[B, Pts, Nk, Hd; T])
TwoWayTransformer
text
sam::TwoWayTransformer<Hd: Dim, Heads: Dim, Inner: Dim, T: Float>
  sub layer_0: TwoWayAttentionBlock<Hd, Heads, Inner, T>
  sub layer_1: TwoWayAttentionBlock<Hd, Heads, Inner, T>
  sub final_attn_token_to_image: MaskAttention<Hd, Hd / 2, Heads, T>
  sub layer_norm_final_attn: LayerNorm<Hd, T>
  pub fn forward<B: Dim, Pts: Dim, Nq: Dim, Nk: Dim>(point_embeddings: Tensor[B, Pts, Nq, Hd; T], image_embeddings: Tensor[B, Pts, Nk, Hd; T], image_pe: Tensor[B, Pts, Nk, Hd; T]) -> (Tensor[B, Pts, Nq, Hd; T], Tensor[B, Pts, Nk, Hd; T])
VisionAttention
text
sam::VisionAttention<D: Dim, Heads: Dim, Wh: Dim, T: Float>
  sub qkv: Linear<D, 3 * D, T>
  sub proj: Linear<D, D, T>
  param rel_pos_h: Tensor[-1 + 2 * Wh, D / Heads; T]
  param rel_pos_w: Tensor[-1 + 2 * Wh, D / Heads; T]
  pub fn forward<Bw: Dim>(x: Tensor[Bw, Wh, Wh, D; T]) -> Tensor[Bw, Wh, Wh, D; T]
VisionEncoder
text
sam::VisionEncoder<D: Dim, Heads: Dim, Inner: Dim, Hd: Dim, T: Float>
  sub patch_embed: Conv2d<3, D, 16, 16, 0, T>
  param pos_embed: Tensor[1, 64, 64, D; T]
  sub layer_0: VisionLayerWindowed<D, Heads, Inner, T>
  sub layer_1: VisionLayerWindowed<D, Heads, Inner, T>
  sub layer_2: VisionLayerGlobal<D, Heads, Inner, T>
  sub layer_3: VisionLayerWindowed<D, Heads, Inner, T>
  sub layer_4: VisionLayerWindowed<D, Heads, Inner, T>
  sub layer_5: VisionLayerGlobal<D, Heads, Inner, T>
  sub layer_6: VisionLayerWindowed<D, Heads, Inner, T>
  sub layer_7: VisionLayerWindowed<D, Heads, Inner, T>
  sub layer_8: VisionLayerGlobal<D, Heads, Inner, T>
  sub layer_9: VisionLayerWindowed<D, Heads, Inner, T>
  sub layer_10: VisionLayerWindowed<D, Heads, Inner, T>
  sub layer_11: VisionLayerGlobal<D, Heads, Inner, T>
  sub neck: VisionNeck<D, Hd, T>
  pub fn forward<B: Dim>(pixel_values: Tensor[B, 3, 1024, 1024; T]) -> Tensor[B, Hd, 64, 64; T]
VisionLayerGlobal
text
sam::VisionLayerGlobal<D: Dim, Heads: Dim, Inner: Dim, T: Float>
  sub layer_norm1: LayerNorm<D, T>
  sub attn: VisionAttention<D, Heads, 64, T>
  sub layer_norm2: LayerNorm<D, T>
  sub mlp: GeluMlp<D, Inner, T>
  pub fn forward<B: Dim>(x: Tensor[B, 64, 64, D; T]) -> Tensor[B, 64, 64, D; T]
VisionLayerWindowed
text
sam::VisionLayerWindowed<D: Dim, Heads: Dim, Inner: Dim, T: Float>
  sub layer_norm1: LayerNorm<D, T>
  sub attn: VisionAttention<D, Heads, 14, T>
  sub layer_norm2: LayerNorm<D, T>
  sub mlp: GeluMlp<D, Inner, T>
  pub fn forward<B: Dim>(x: Tensor[B, 64, 64, D; T]) -> Tensor[B, 64, 64, D; T]
VisionNeck
text
sam::VisionNeck<D: Dim, Hd: Dim, T: Float>
  sub conv1: Conv2d<D, Hd, 1, 1, 0, T>
  sub ln1: LayerNormCHW<Hd, T>
  sub conv2: Conv2d<Hd, Hd, 3, 1, 1, T>
  sub ln2: LayerNormCHW<Hd, T>
  pub fn forward<B: Dim>(x: Tensor[B, 64, 64, D; T]) -> Tensor[B, Hd, 64, 64; T]