Models / sd-vae-ft-mse

SD VAE ft-MSE (decoder)

Stability AI's MSE-finetuned autoencoder for Stable Diffusion, decoder half: group-normalized residual blocks, one spatial self-attention, and nearest-neighbour upsampling turn a 4-channel latent into an RGB image.

49.5M parameterssd-vaeMITimage-generationvisionconvolutionaldiffusionautoencoder
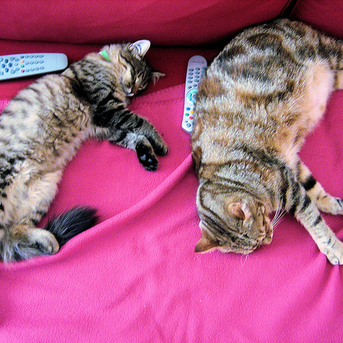
Input
Input
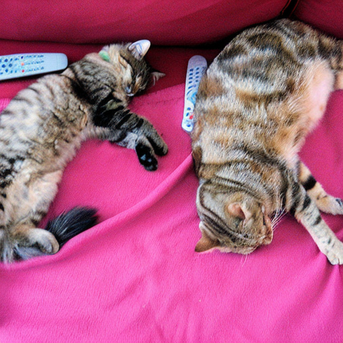
Output
Output, Linnet torch (generated source), bf16, cuda

A COCO val2017 photo (512x512) encoded to a 64x64x4 latent by diffusers' AutoencoderKL encoder (Linnet implements only the decoder), then decoded by this card with Linnet torch in bf16.

PSNR, Linnet vs the input
23.29 dB
PSNR, diffusers vs the input
23.29 dB
PSNR, Linnet vs diffusers
54.82 dB
Reference
diffusers AutoencoderKL.decode, bf16